New in Razuna: Discover the Content Hidden Inside Your PDFs
A product photo on page 18. A diagram tucked into a proposal. A scanned specification with no selectable text. Your documents contain far more than their filenames suggest—and far more than a basic text index can see.
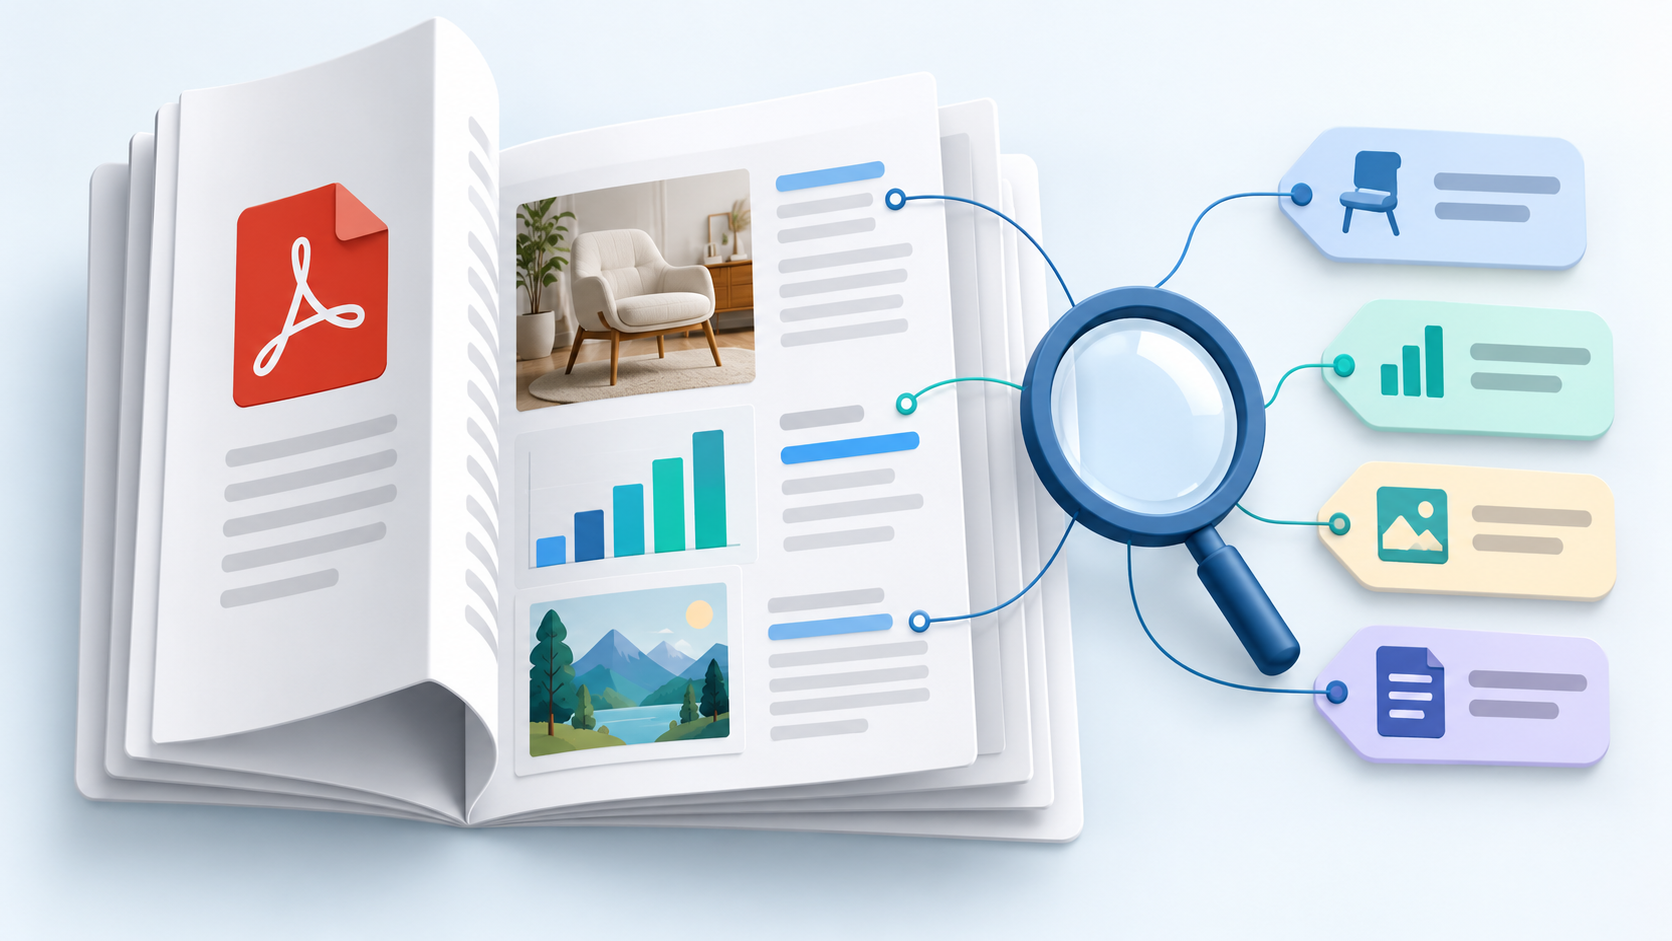
Razuna’s new PDF and document extraction brings that content into view. Alongside indexing document text, Razuna now analyzes the visual content inside document pages and applies AI classification. The images and information you placed inside a PDF can help you find that PDF again.
Search beyond the text layer
Text indexing is useful when you know a phrase, product name, or reference that appears in a document. But a PDF can also contain photographs, illustrations, charts, screenshots, and pages that are entirely scanned images. Much of their meaning never appears in the selectable text.
Consider a product catalog. Its text might list model numbers and dimensions, while its photographs show the materials, colors, shapes, and settings that a customer actually remembers. Someone looking for a blue upholstered chair may have no idea which model number to search for.
Razuna analyzes document pages visually as well as extracting their text. It examines page details and brings the resulting descriptions and classification into the document’s metadata. That gives your library more useful information to search.
The content inside the PDF becomes part of discovery
Images do not stop being valuable assets when they become part of a document. A photograph in a brochure, artwork in a portfolio, or a diagram in a report can contain the very detail that makes the document relevant.
With deeper analysis, those details can contribute to AI descriptions, keywords, and classification. Scanned text can also be recognized, helping make information discoverable even when the PDF has no native text layer.
The result stays connected to the original document. You find the catalog, proposal, or report containing the relevant material, keeping the surrounding context close at hand. This feature analyzes content within the pages; it does not turn every image into a separate downloadable library asset or unpack arbitrary PDF attachments.
How much more information can you find?
The biggest change is the number of ways a document can become relevant to a search.
As an illustration, imagine a library of 100 catalogs, each containing 20 product photographs. That is 2,000 visual items whose content may be absent from a text-only index. Analyzing those pages creates opportunities to describe products, colors, materials, and scenes that the catalog’s text never names.
Those numbers illustrate the opportunity, not a measured Razuna benchmark. They do not mean 2,000 new files or a guaranteed increase in search results. The gain depends on what your documents contain, image quality, and how much useful text was already available.
A mostly textual report may gain a richer summary and classification. An image-heavy brochure or scanned document may gain an entirely new layer of searchable information. The practical benefit is finding material that was already in your library but difficult to discover.
AI classification makes the extra information useful
Extracting more content is only part of the job. It also needs to become useful metadata.
Razuna combines analysis of document text and page visuals to build descriptions, keywords, and classification. Depending on the content, that can include document types, subjects, visible objects, and relevant people or brands. Document classification can follow your workspace’s instructions and configured response language.
That means less manual effort describing every document from scratch, and more context for colleagues who did not upload the file or create the original material. AI-generated metadata remains something your team can review and refine.
More value from the documents you already keep
Marketing teams can rediscover visual material inside older campaign presentations. Sales teams can locate proposals using the products or subjects they contain. Design teams can find portfolios and reference documents through their artwork. Operations teams can search information in scanned records that previously required opening and reading each file.
Better discovery also helps teams assess existing work before recreating it. Finding the right brochure or presentation provides a starting point for reuse, with the original document available for checking context and suitability.
The same approach extends to supported Word, PowerPoint, Excel, OpenDocument, and RTF files through document rendering. PDFs, presentations, and other documents can contribute both their text and their visual content to a more informative library.
Try a document whose best content is inside
With automatic AI classification enabled in your workspace, try a document containing a mix of text and images. Once processing finishes, review its description and keywords, then search for a distinctive subject or phrase from within its pages.
Start with a catalog, a presentation, or a scanned PDF you know well. It is a simple way to see how much useful information has been sitting inside your documents—and how much easier it can be to find.